> ## Documentation Index
> Fetch the complete documentation index at: https://docs.capy.ai/llms.txt
> Use this file to discover all available pages before exploring further.
# Models & pricing
Capy bills for two things: model tokens and machine server time. Usage draws from one balance, in dollars, shared by your whole organization.
A subscription plan includes a set amount of usage each month at a discount. You can also add balance directly (minimum \$5) and enable [auto-reload](/admin/billing#auto-reload).
## Plans
Three plans, sized by the monthly credit grant. Annual billing is 12 months upfront at 20% off, with the same credits granted monthly.
| Plan | Monthly | Annual (per month) | Credits per month |
| - | - | - | - |
| **Capy Lite** | \$20 | \$16 | \$20 of credits |
| **Capy Pro** | \$100 | \$80 | \$105 of credits (+5%) |
| **Capy Max** | \$200–\$1,000 | \$160–\$800 | 110% of the price (+10%) |
| **Enterprise** | Custom | Custom | Custom |
Every plan from Lite up can connect your own API keys and gateways. Higher plans raise how much cloud machine capacity you can run.
Capy Max comes in \$100 steps from \$200 to \$1,000. Every step grants 110% of its price in credits, so \$500/mo buys \$550 of credits.
**Try Capy Lite for \$1.** Your first 7 days cost \$1 with a verified card, then \$20/mo. One intro per card and per organization. Monthly Lite only.
If you use your credits up mid-month, top up manually or with [auto-reload](/admin/billing#auto-reload).
## No seats
Every plan includes unlimited members. There is no per-seat price, no included-member limit, and no charge for inviting anyone. Plans size usage, nothing else.
## Models
Every model appears once in the model picker, named by the company that makes it: `openai/gpt-6-sol`, `anthropic/claude-opus-5`. What a model runs on depends on your [connections](#connections): the first subscription or key in your list that covers it, or Capy credits if none does.
Prices are per 1M tokens and apply to usage on Capy credits. Usage on a subscription or key costs nothing from your balance. A ✓ in the BYOK column means you can run the model on your own key from that provider.
| Model | ID | Context | Input (per 1M) | Output (per 1M) | BYOK |
| - | - | - | - | - | - |
| **GPT-6 Astra** | `openai/gpt-6-astra` | 1.05M | ≤272K: \$10.00 (cached \$1.00)
>272K: \$20.00 (cached \$2.00) | ≤272K: \$50.00
>272K: \$75.00 | ✓ |
| **GPT-6.1 Sol** | `openai/gpt-6.1-sol` | 1.05M | ≤272K: \$2.00 (cached \$0.10)
>272K: \$4.00 (cached \$0.20) | ≤272K: \$10.00
>272K: \$15.00 | ✓ |
| **GPT-6 Sol** | `openai/gpt-6-sol` | 1.05M | ≤272K: \$2.00 (cached \$0.20)
>272K: \$4.00 (cached \$0.40) | ≤272K: \$10.00
>272K: \$15.00 | ✓ |
| **GPT-6 Luna** | `openai/gpt-6-luna` | 1.05M | ≤272K: \$0.10 (cached \$0.01)
>272K: \$0.20 (cached \$0.02) | ≤272K: \$0.50
>272K: \$0.75 | ✓ |
| **GPT-5.6 Sol** | `openai/gpt-5.6-sol` | 1.05M | ≤272K: \$4.00 (cached \$0.40)
>272K: \$8.00 (cached \$0.80) | ≤272K: \$20.00
>272K: \$30.00 | ✓ |
| **GPT-5.6 Terra** | `openai/gpt-5.6-terra` | 1.05M | ≤272K: \$2.00 (cached \$0.20)
>272K: \$4.00 (cached \$0.40) | ≤272K: \$12.00
>272K: \$18.00 | ✓ |
| **GPT-5.6 Luna** | `openai/gpt-5.6-luna` | 1.05M | ≤272K: \$0.20 (cached \$0.02)
>272K: \$0.40 (cached \$0.04) | ≤272K: \$1.20
>272K: \$1.80 | ✓ |
| **GPT-5.5** | `openai/gpt-5.5` | 1.05M | ≤272K: \$5.00 (cached \$0.50)
>272K: \$10.00 (cached \$1.00) | ≤272K: \$30.00
>272K: \$45.00 | ✓ |
| **GPT-5.5 Pro** | `openai/gpt-5.5-pro` | 1.05M | ≤272K: \$30.00
>272K: \$60.00 | ≤272K: \$180.00
>272K: \$270.00 | ✓ |
| **GPT-5.4 Mini** | `openai/gpt-5.4-mini` | 400K | \$0.75 (cached \$0.075) | \$4.50 | ✓ |
| **GPT-5.4** | `openai/gpt-5.4` | 1.05M | ≤272K: \$2.50 (cached \$0.25)
>272K: \$5.00 (cached \$0.50) | ≤272K: \$15.00
>272K: \$22.50 | ✓ |
| **GPT-5.3 Codex** | `openai/gpt-5.3-codex` | 400K | \$1.75 (cached \$0.175) | \$14.00 | ✓ |
| **Claude Fable 5.1** | `anthropic/claude-fable-5-1` | 1M | \$10.00 (cached \$0.25) | \$50.00 | ✓ |
| **Claude Opus 5.5** (default) | `anthropic/claude-opus-5-5` | 1M | \$4.00 (cached \$0.20) | \$20.00 | ✓ |
| **Claude Sonnet 5.5** | `anthropic/claude-sonnet-5-5` | 1M | \$2.00 (cached \$0.20) | \$10.00 | ✓ |
| **Claude Fable 5** | `anthropic/claude-fable-5` | 1M | \$10.00 (cached \$1.00) | \$50.00 | ✓ |
| **Claude Opus 5** | `anthropic/claude-opus-5` | 1M | \$5.00 (cached \$0.50) | \$25.00 | ✓ |
| **Claude Sonnet 5** | `anthropic/claude-sonnet-5` | 1M | \$2.00 (cached \$0.20) | \$10.00 | ✓ |
| **Claude Haiku 4.5** | `anthropic/claude-haiku-4-5` | 200K | \$1.00 (cached \$0.10) | \$5.00 | ✓ |
| **Claude Opus 4.8** | `anthropic/claude-opus-4-8` | 1M | \$5.00 (cached \$0.50) | \$25.00 | ✓ |
| **Claude Opus 4.7** | `anthropic/claude-opus-4-7` | 1M | \$5.00 (cached \$0.50) | \$25.00 | ✓ |
| **Claude Sonnet 4.6** | `anthropic/claude-sonnet-4-6` | 1M | \$3.00 (cached \$0.30) | \$15.00 | ✓ |
| **Claude Opus 4.6** | `anthropic/claude-opus-4-6` | 1M | \$5.00 (cached \$0.50) | \$25.00 | ✓ |
| **Claude Opus 4.5** | `anthropic/claude-opus-4-5` | 200K | \$5.00 (cached \$0.50) | \$25.00 | ✓ |
| **Grok 4.7** | `xai/grok-4.7` | 500K | \<200K: \$2.00 (cached \$0.50)
≥200K: \$4.00 (cached \$1.00) | \<200K: \$6.00
≥200K: \$12.00 | ✓ |
| **Grok 4.6** | `xai/grok-4.6` | 500K | \<200K: \$2.00 (cached \$0.50)
≥200K: \$4.00 (cached \$1.00) | \<200K: \$6.00
≥200K: \$12.00 | ✓ |
| **Grok 4.5** | `xai/grok-4.5` | 500K | \<200K: \$2.00 (cached \$0.30)
≥200K: \$4.00 (cached \$0.60) | \<200K: \$6.00
≥200K: \$12.00 | ✓ |
| **Kimi K3** | `moonshotai/kimi-k3` | 1.05M | \$3.00 (cached \$0.30) | \$15.00 | |
| **Kimi K2.7 Code** | `moonshotai/kimi-k2.7-code` | 262K | \$0.95 (cached \$0.19) | \$4.00 | |
| **Kimi K2.6** | `moonshotai/kimi-k2.6` | 262K | \$0.95 (cached \$0.16) | \$4.00 | |
| **GLM-5.3** | `zai/glm-5.3` | 1.05M | \$1.40 (cached \$0.26) | \$4.40 | |
| **GLM-5.3-Flash** | `zai/glm-5.3-flash` | 1.05M | \$0.15 (cached \$0.03) | \$0.50 | |
| **GLM-5.2** | `zai/glm-5.2` | 1.05M | \$1.40 (cached \$0.26) | \$4.40 | |
| **GLM-5V-Turbo** | `zai/glm-5v-turbo` | 203K | \$1.20 (cached \$0.24) | \$4.00 | |
| **GLM-5-Turbo** | `zai/glm-5-turbo` | 203K | \$1.20 (cached \$0.24) | \$4.00 | |
| **DeepSeek V4.1 Flash** | `deepseek/deepseek-v4.1-flash` | 1.05M | \$0.30 (cached \$0.006) | \$1.20 | |
| **DeepSeek V4 Pro** | `deepseek/deepseek-v4-pro` | 1.05M | \$1.74 (cached \$0.145) | \$3.48 | |
| **DeepSeek V4 Flash 0731** | `deepseek/deepseek-v4-flash-0731` | 1.05M | \$0.14 (cached \$0.028) | \$0.28 | |
| **Gemini 3.8 Flash** | `google/gemini-3.8-flash` | 1.05M | \$0.75 (cached \$0.075) | \$3.75 | ✓ |
| **Gemini 3.7 Flash** | `google/gemini-3.7-flash` | 1.05M | \$0.75 (cached \$0.075) | \$3.75 | ✓ |
| **Gemini 3.6 Flash** | `google/gemini-3.6-flash` | 1.05M | \$1.50 (cached \$0.15) | \$7.50 | ✓ |
| **Qwen3.8 Max** | `qwen/qwen3.8-max` | 1M | \$2.00 (cached \$0.25) | \$6.00 | |
| **Qwen3.8 Flash** | `qwen/qwen3.8-flash` | 1M | \$0.15 (cached \$0.016) | \$0.47 | |
| **Qwen3.7 Max** | `qwen/qwen3.7-max` | 1M | \$1.48 (cached \$0.295) | \$4.42 | |
| **Qwen3.7 Plus** | `qwen/qwen3.7-plus` | 1M | ≤256K: \$0.32 (cached \$0.064)
>256K: \$0.96 (cached \$0.192) | ≤256K: \$1.28
>256K: \$3.84 | |
| **Qwen3.6 Plus** | `qwen/qwen3.6-plus` | 1M | ≤256K: \$0.325
>256K: \$1.30 | ≤256K: \$1.95
>256K: \$3.90 | |
| **MiniMax M3** | `minimax/minimax-m3` | 524K | \$0.30 (cached \$0.06) | \$1.20 | |
| **MiniMax M2.7** | `minimax/minimax-m2.7` | 205K | \$0.30 (cached \$0.06) | \$1.20 | |
| **MiMo-V2.6 Pro** | `xiaomi/mimo-v2.6-pro` | 1.05M | \$0.435 (cached \$0.0036) | \$0.87 | |
| **MiMo-V2.5 Pro** | `xiaomi/mimo-v2.5-pro` | 1.05M | \$0.435 (cached \$0.0036) | \$0.87 | |
| **MiMo-V2.5** | `xiaomi/mimo-v2.5` | 1.05M | \$0.14 (cached \$0.0028) | \$0.28 | |
| **Hy4 Preview** | `tencent/hy4-preview` | 1.05M | \$0.834 (cached \$0.042) | \$2.50 | |
| **Hy3** | `tencent/hy3` | 262K | \$0.132 (cached \$0.033) | \$0.528 | |
| **LongCat-2.0** | `meituan/longcat-2.0` | 1.05M | \$0.30 (cached \$0.006) | \$1.20 | |
| **Muse Spark 1.3** | `meta/muse-spark-1.3` | 1.05M | \$1.25 (cached \$0.15) | \$4.25 | |
| **Muse Spark 1.2** | `meta/muse-spark-1.2` | 1.05M | \$1.25 (cached \$0.15) | \$4.25 | |
| **Muse Spark 1.1** | `meta/muse-spark-1.1` | 1.05M | \$1.25 (cached \$0.15) | \$4.25 | |
| **Muse Glimmer 30B** | `meta/muse-glimmer-30b` | 131K | \$0.30 (cached \$0.04) | \$1.10 | |
## Subscriptions
A connected Codex, GitHub Copilot, or SuperGrok subscription covers these models, and usage counts against that plan's limits instead of your balance. Azure runs through an organization account. Connect one under [connections](#connections).
| Model | ID | Runs on | Context |
| - | - | - | - |
| **GPT-6 Astra** | `openai/gpt-6-astra` | Codex | 1.05M |
| **GPT-6.1 Sol** | `openai/gpt-6.1-sol` | Codex | 1.05M |
| **GPT-6 Sol** | `openai/gpt-6-sol` | Codex | 1.05M |
| **GPT-6 Luna** | `openai/gpt-6-luna` | Codex | 1.05M |
| **GPT-5.6 Sol** | `openai/gpt-5.6-sol` | Codex | 400K |
| **GPT-5.6 Terra** | `openai/gpt-5.6-terra` | Codex | 400K |
| **GPT-5.6 Luna** | `openai/gpt-5.6-luna` | Codex | 400K |
| **GPT-5.5** | `openai/gpt-5.5` | Codex | 400K |
| **GPT-5.6 Sol** | `openai/gpt-5.6-sol` | Copilot | 1.05M |
| **GPT-5.6 Terra** | `openai/gpt-5.6-terra` | Copilot | 1.05M |
| **GPT-5.6 Luna** | `openai/gpt-5.6-luna` | Copilot | 1.05M |
| **GPT-5.5** | `openai/gpt-5.5` | Copilot | 1.05M |
| **GPT-5.4 Mini** | `openai/gpt-5.4-mini` | Copilot | 400K |
| **GPT-5.4** | `openai/gpt-5.4` | Copilot | 1.05M |
| **GPT-5.3 Codex** | `openai/gpt-5.3-codex` | Copilot | 400K |
| **Claude Haiku 4.5** | `anthropic/claude-haiku-4-5` | Copilot | 200K |
| **Claude Opus 4.8** | `anthropic/claude-opus-4-8` | Copilot | 200K |
| **Claude Opus 4.7** | `anthropic/claude-opus-4-7` | Copilot | 200K |
| **Claude Sonnet 4.6** | `anthropic/claude-sonnet-4-6` | Copilot | 200K |
| **Claude Opus 4.6** | `anthropic/claude-opus-4-6` | Copilot | 200K |
| **Claude Opus 4.5** | `anthropic/claude-opus-4-5` | Copilot | 200K |
| **Gemini 3.7 Flash** | `google/gemini-3.7-flash` | Copilot | 1M |
| **Gemini 3.6 Flash** | `google/gemini-3.6-flash` | Copilot | 1M |
| **Grok 4.7** | `xai/grok-4.7` | SuperGrok | 500K |
| **Grok 4.6** | `xai/grok-4.6` | SuperGrok | 500K |
| **Grok 4.5** | `xai/grok-4.5` | SuperGrok | 500K |
| **GPT-5.6 Sol** | `openai/gpt-5.6-sol` | Azure (organization) | 1.05M |
| **Claude Fable 5** | `anthropic/claude-fable-5` | Azure (organization) | 1M |
## Fast mode
Models with a Fast toggle run through the provider's priority tier at a higher price. When no fast host is available, the request serves at the standard tier and bills at standard rates. Fast rates per 1M tokens:
| Model | Fast input (per 1M) | Fast output (per 1M) |
| - | - | - |
| **GPT-6 Astra** | \$20.00 (cached \$2.00) | \$100.00 |
| **GPT-6.1 Sol** | \$4.00 (cached \$0.20) | \$20.00 |
| **GPT-6 Sol** | \$4.00 (cached \$0.40) | \$20.00 |
| **GPT-6 Luna** | \$0.20 (cached \$0.02) | \$1.00 |
| **GPT-5.6 Sol** | \$8.00 (cached \$0.80) | \$40.00 |
| **GPT-5.6 Terra** | \$4.00 (cached \$0.40) | \$24.00 |
| **GPT-5.6 Luna** | \$0.40 (cached \$0.04) | \$2.40 |
| **GPT-5.5** | \$12.50 (cached \$1.25) | \$75.00 |
| **GPT-5.4 Mini** | \$1.50 (cached \$0.15) | \$9.00 |
| **GPT-5.4** | \$5.00 (cached \$0.50) | \$30.00 |
| **GPT-5.3 Codex** | \$3.50 (cached \$0.35) | \$28.00 |
| **Claude Opus 5.5** | \$8.00 (cached \$0.40) | \$40.00 |
| **Claude Opus 5** | \$10.00 (cached \$1.00) | \$50.00 |
| **Claude Opus 4.8** | \$10.00 (cached \$1.00) | \$50.00 |
| **Grok 4.7** | \<200K: \$4.00 (cached \$1.00)
≥200K: \$8.00 (cached \$2.00) | \<200K: \$12.00
≥200K: \$24.00 |
| **Grok 4.6** | \<200K: \$4.00 (cached \$1.00)
≥200K: \$8.00 (cached \$2.00) | \<200K: \$12.00
≥200K: \$24.00 |
| **Grok 4.5** | \<200K: \$4.00 (cached \$0.60)
≥200K: \$8.00 (cached \$1.20) | \<200K: \$12.00
≥200K: \$24.00 |
## Reasoning effort
Most models expose a reasoning effort, from `none` up to `max`. Each entry supports its own subset, shown in the picker. An unsupported effort fails before the request is sent. Capy never quietly approximates it with a different setting.
## Connections
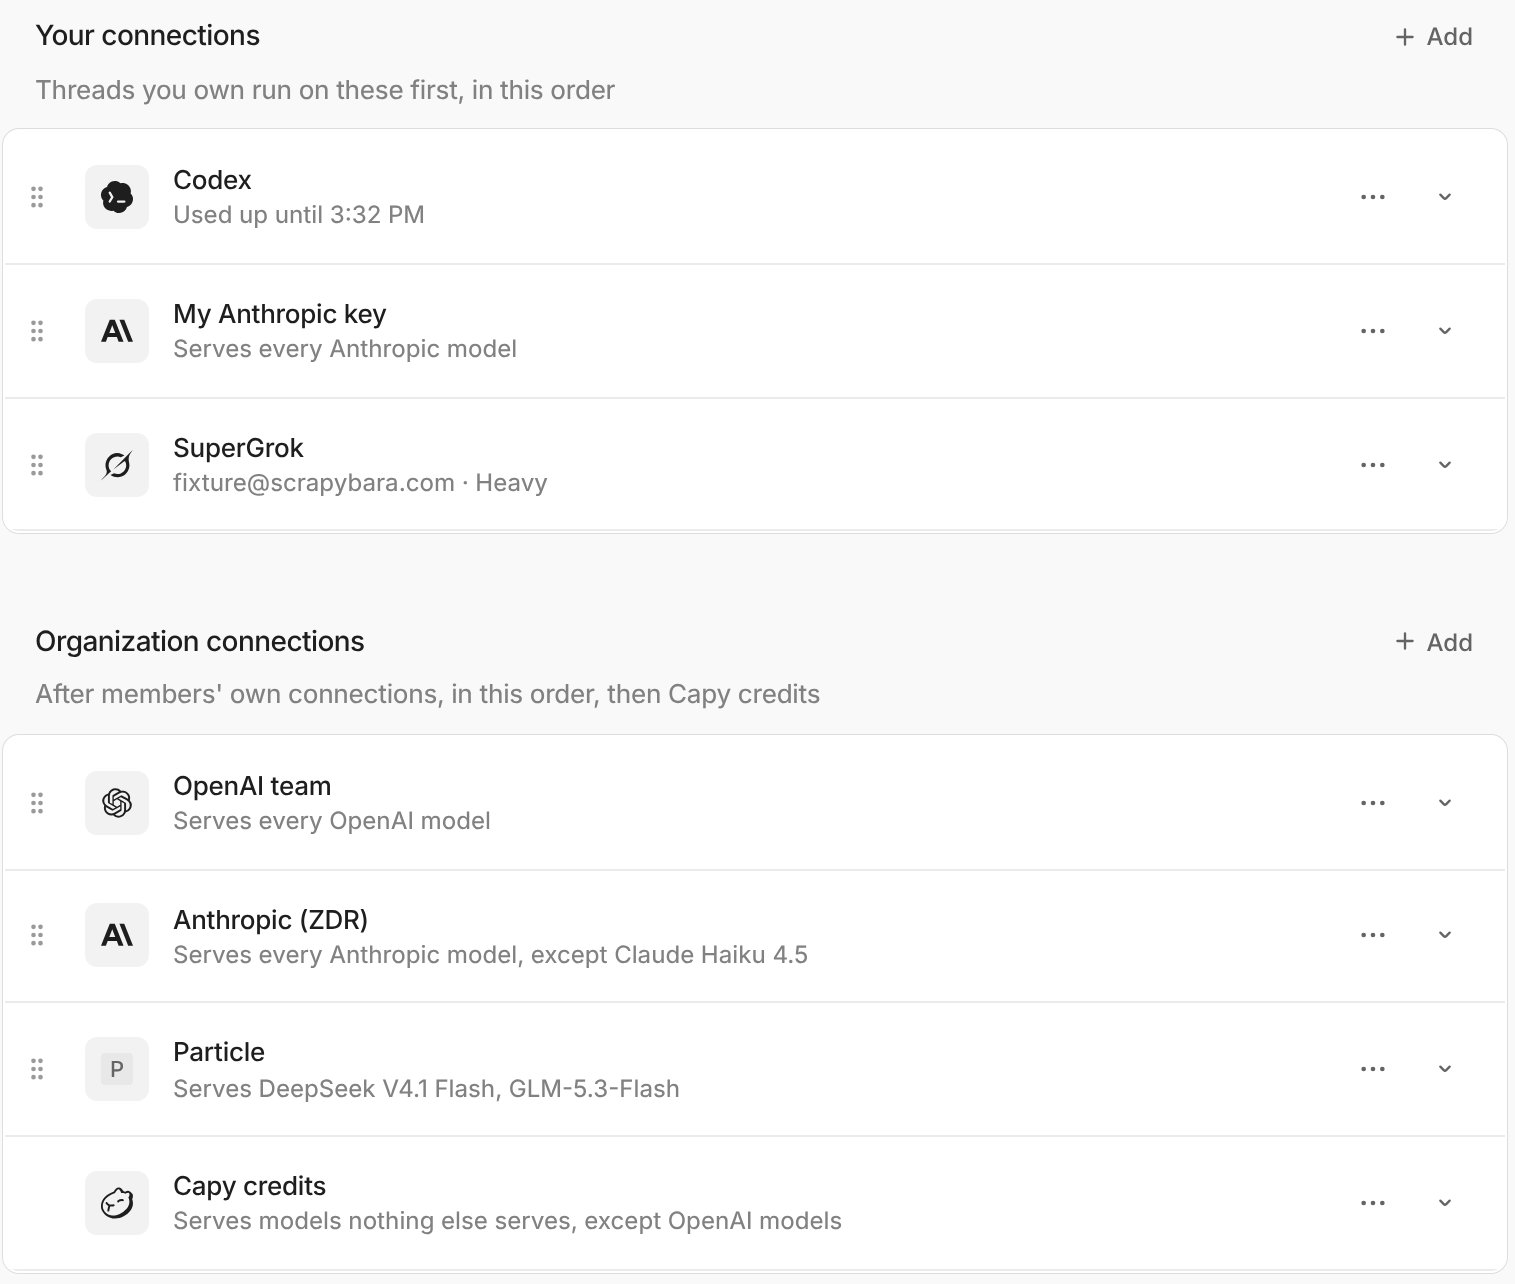
Out of the box every model runs on **Capy credits**, the balance your organization buys. Connect a subscription or an API key and the models it covers run on that instead, at no cost to your balance. A thread uses the first connection in the list that covers its model: yours first, in your order, then your organization's, then Capy credits.
[Settings → Models](https://capy.ai/settings/models) shows your connections, then the organization's, then Capy credits. Drag a connection to change its place; Capy credits always stays last. Expand a connection to choose which models it covers.
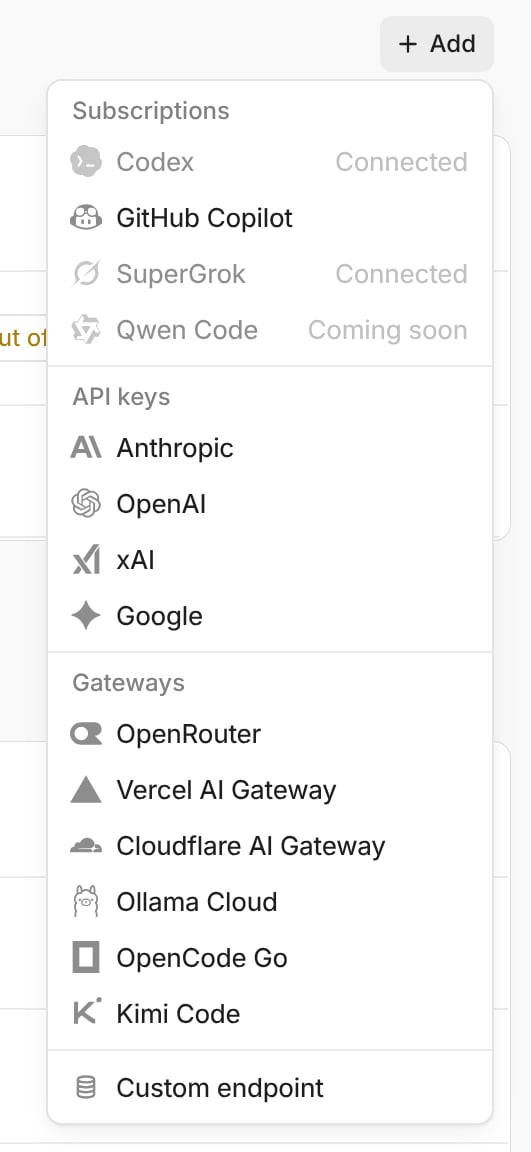
 Click **Add**. A subscription is personal and signs in through your account with that provider; for Codex, turn on **Device code authorization** in ChatGPT's security settings first. An API key, a gateway like OpenRouter, or any OpenAI-compatible endpoint can be personal or the organization's, and needs a plan, starting with Lite.
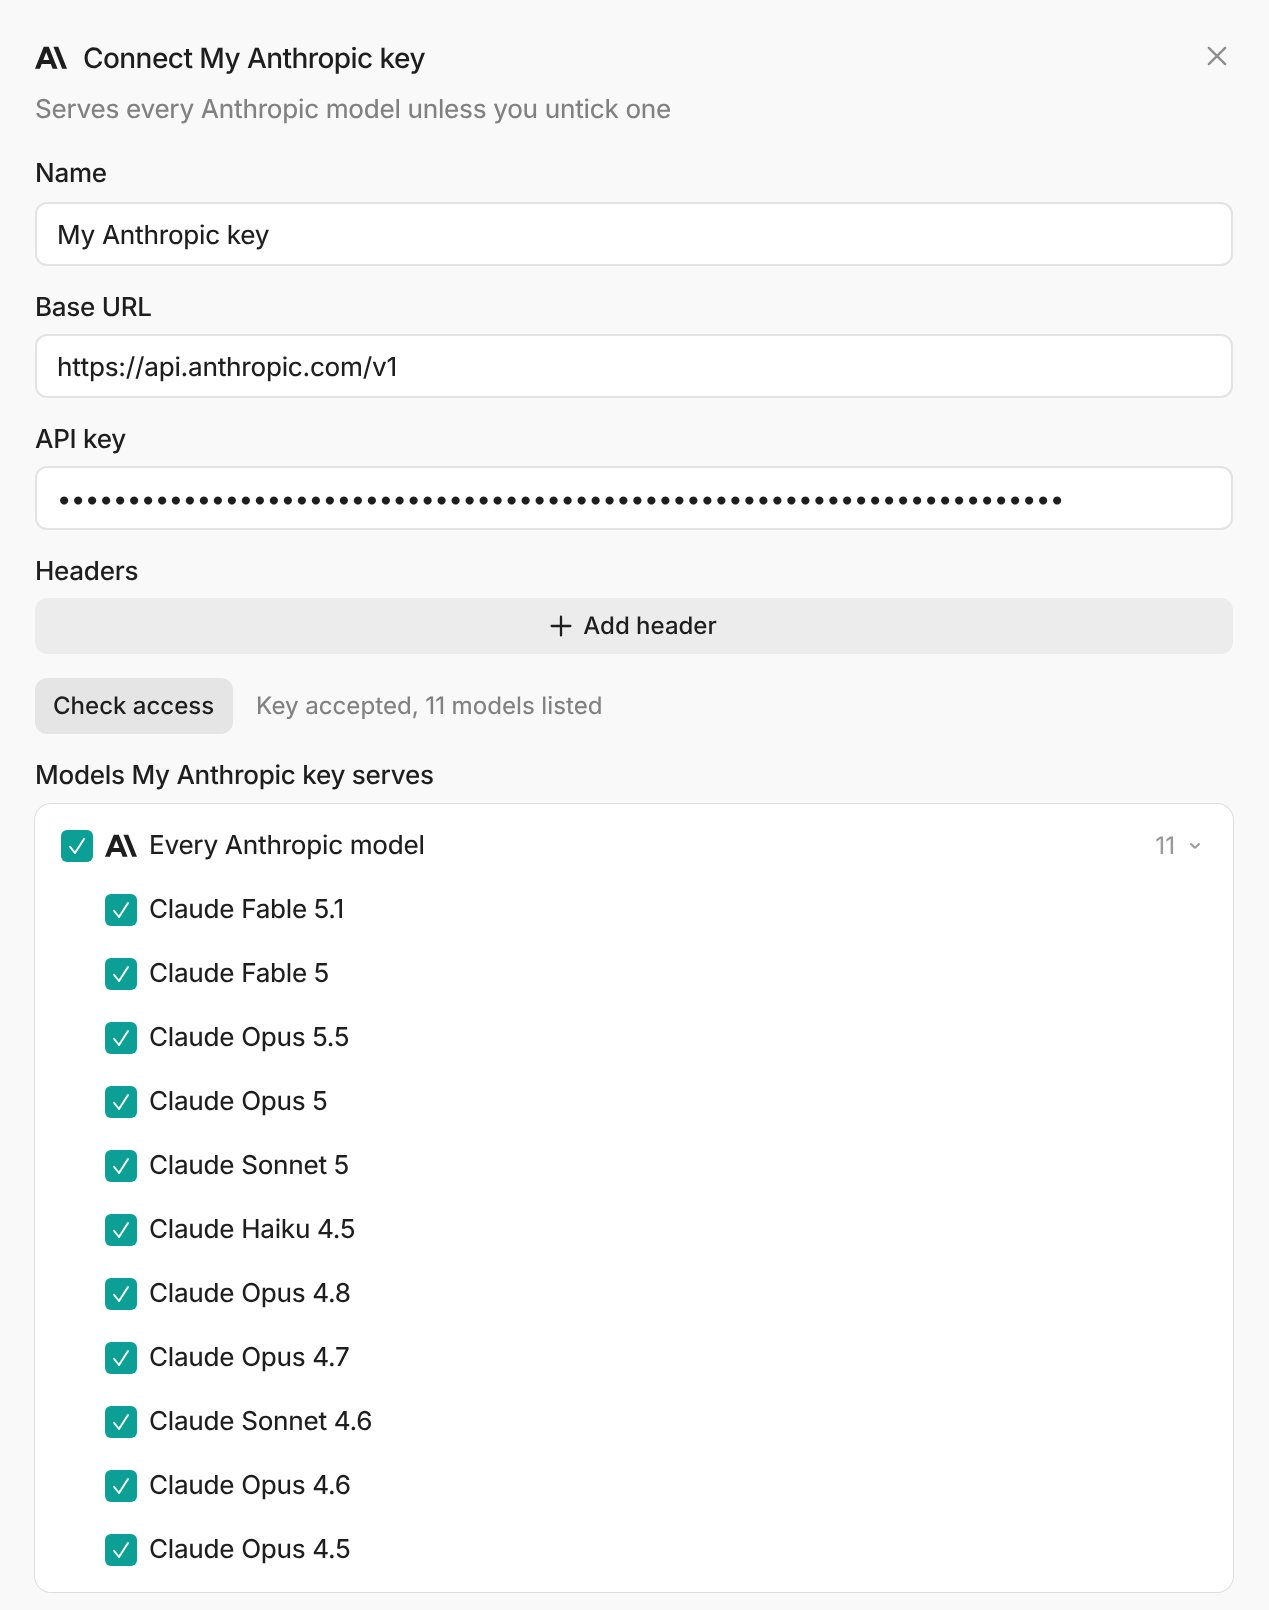
 Paste the key and click **Check access**. Capy lists the models the key can run, all selected; uncheck any you don't want on this key. An Anthropic, OpenAI, xAI, or Google key also covers new models from that company as they come out. Click **Connect**.
 Later, a key's **⋯** menu has **Test connection**, **Replace key**, **Rename**, **Custom headers**, and **Remove**; a subscription's has **Reconnect** and **Disconnect**.
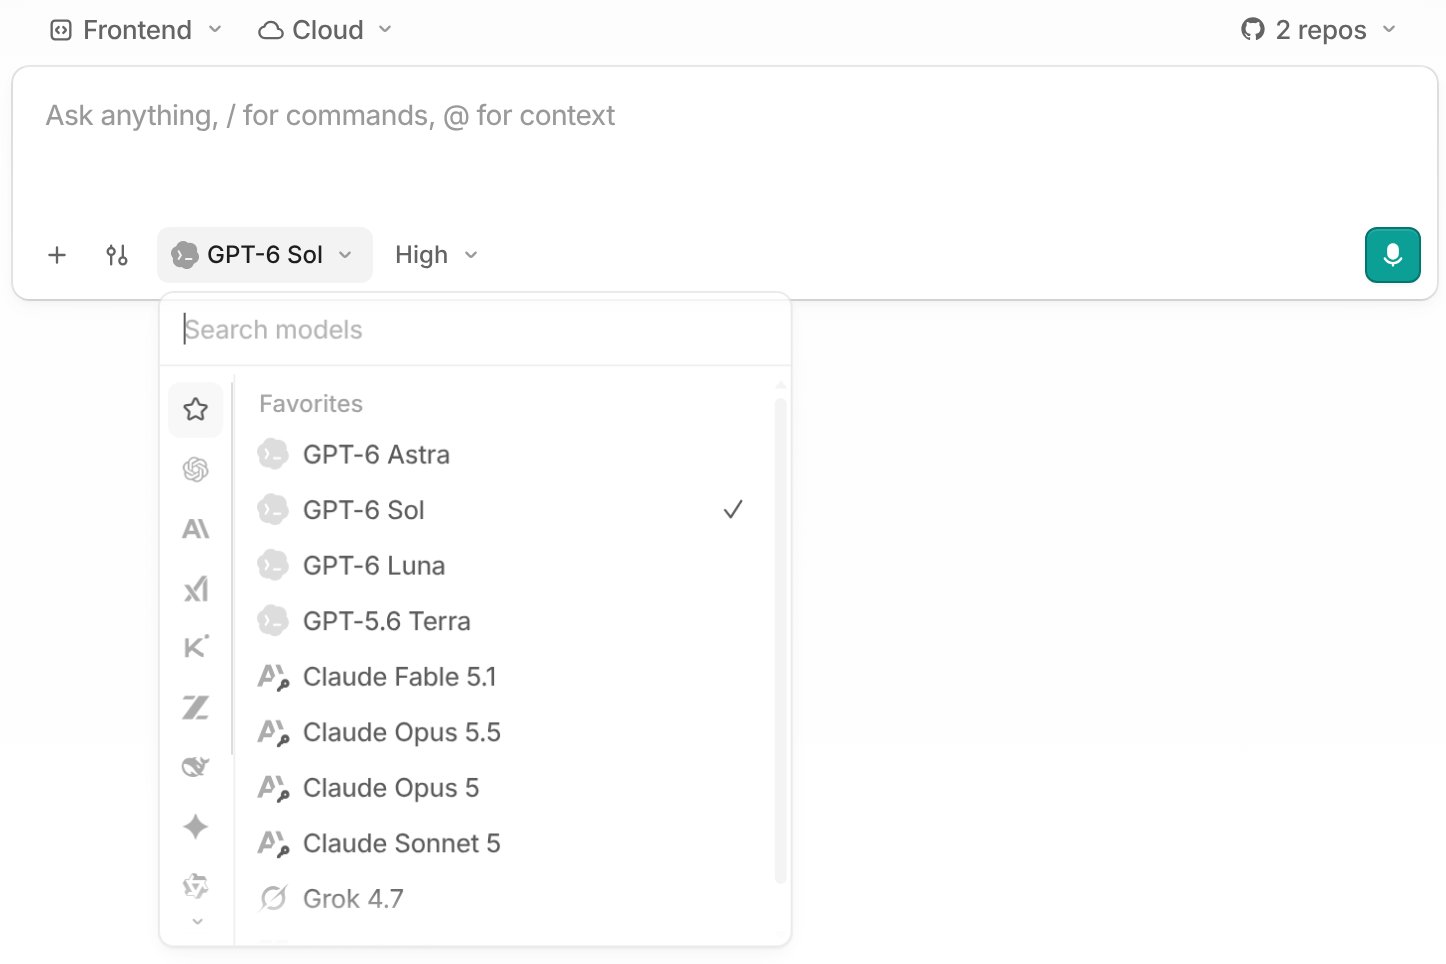
In the model picker, each model shows what it runs on: a subscription's icon, a key badge, or nothing for Capy credits. Hover the logo for the words, `Runs on your Codex subscription`. The thread's cost breakdown marks usage on a subscription or key **Unbilled**.
 ### How it works
* **One connection at a time.** Each message uses the first connection in the list that covers the model: the thread owner's connections, top to bottom, then the organization's, then Capy credits. A colleague writing in your thread runs on your connections, never their own.
* **Each connection covers a set of models.** A subscription covers what its plan includes. A key covers every model from its company unless you uncheck one. Capy credits has the same checklist, so an admin can keep a company's models off the organization's balance.
* **What you pay.** Usage on a subscription counts against that plan's limits. Usage on a key is billed by the provider. Only usage on Capy credits and machine time come out of your balance.
### When a subscription or key runs out
A subscription is **used up** when it hits its plan's limit, and works again when the limit resets. A brief rate limit is retried and does not count. A connection can also be **turned off**, a subscription **signed out**, and a key **rejected**. When the first connection in the list cannot run the model for one of these reasons, what the thread does next is one setting on the Models page: an admin sets it for the organization, and can let each member set it for their own threads.
A key that has no credit left is different: the message fails with the provider's error, the setting below does not apply, and the key works again once you top the account up where you manage it.
| Setting | Next in line is another subscription or key | Next in line is Capy credits |
| - | - | - |
| **Ask me** | Stops and asks | Stops and asks |
| **Ask before Capy credits** (default) | Moves on, with a note in the thread | Stops and asks |
| **Keep going** | Moves on, with a note in the thread | Moves on, with a note in the thread |
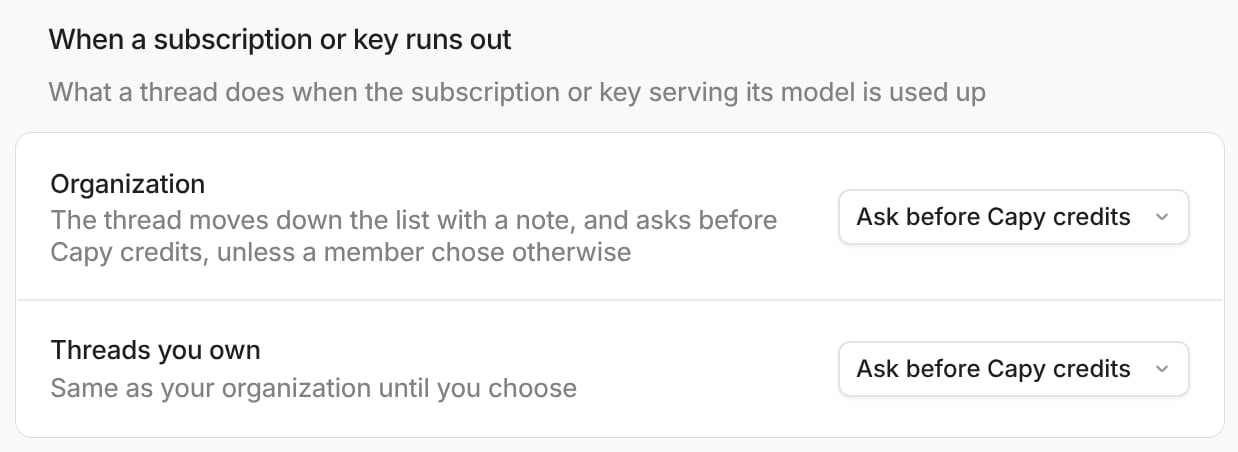 When the thread moves on, it posts one note, `Codex is used up until 11:08 PM. Running on OpenAI team key.`, and goes back to the earlier connection as soon as that works again. When it stops, it shows one card with one question.
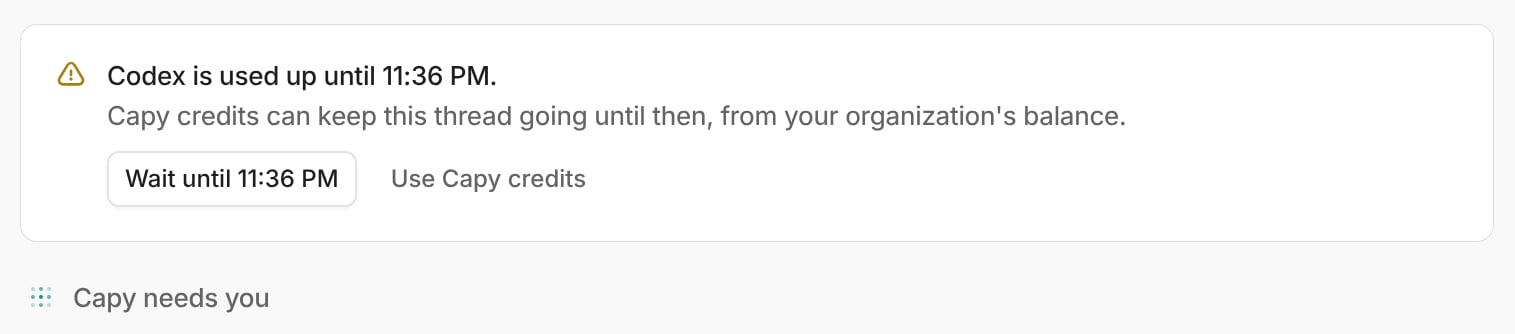 **Wait** holds the thread until the reset. **Use** continues on the next connection, and from then on the thread keeps going on its own, Capy credits included. Only the thread's owner can answer. The same card shows in Slack with the same two buttons, and the CLI prints it with `/wait` and `/continue`. If nothing in the list can run the model, the thread stops and says so.
### Organization settings
Admins manage the organization's connections and these switches on the Models page; members can see them but not change them.
* **Members can connect their own subscriptions and keys**, on by default. Off hides members' own lists and runs every thread on the organization's connections.
* **Members can choose what happens when a subscription or key runs out**, off by default.
* In a model's **⋯** menu in the Models table: **Only OpenAI team key** (named after the organization's key for that model) keeps the model on the organization's keys, never a member's own connection or Capy credits, for teams with data-handling requirements; **Turn off** removes the model from every picker in the organization; **Compact at** sets how full a thread's context can get before it summarizes its history.
## Per-subagent models
Threads and subagents pick models independently. The agent can run a subagent on a cheaper model for mechanical work, or a stronger one for a hard subsystem. Subagents follow parent thread models by default.
## When your balance runs out
A thread on Capy credits stops with an out-of-credits card when the balance runs out. Add balance manually or with [auto-reload](/admin/billing#auto-reload), then send a message; the thread picks up where it left off. A thread on a subscription or key never spends Capy credits without asking first unless your organization set it to keep going; see [when a subscription or key runs out](#when-a-subscription-or-key-runs-out).
## Machine pricing
Each thread runs on its own VM machine, billed hourly by size:
| Size | vCPU | RAM | Disk | Cost/hour |
| - | - | - | - | - |
| Small | 1 | 4 GB | 64 GB | \$0.10 |
| Medium | 2 | 8 GB | 64 GB | \$0.20 |
| Large | 4 | 16 GB | 64 GB | \$0.40 |
| Ultra | 8 | 32 GB | 64 GB | \$0.80 |
| Hyper | 16 | 64 GB | 128 GB | \$1.60 |
| Big Guy (enterprise) | 16 | 128 GB | 256 GB | \$3.20 |
Large is the default. You pay while a machine is awake, plus a two-minute wind-down when it goes to sleep. A sleeping machine costs nothing, but waking it to extend its uptime for ports, desktop, file viewer will incur a charge. See [machines](/machines).
## Enterprise
Need more than Capy Max's \$1,000/month in credits, custom pricing, or invoiced billing with net terms? We set up a custom plan. Everything else works the same as on standard plans.
[Contact us →](https://cal.com/team/capy/enterprise)
## FAQ
Subscribe to monthly Capy Lite with a verified card and your first 7 days cost \$1, then \$20/mo unless you cancel. One intro per card and per organization, ever.
No. Every plan includes unlimited members with no per-seat price, so inviting someone never creates a member charge.
A thread on Capy credits stops with an out-of-credits card. Add balance or let auto-reload top up, then send a message; nothing resumes on its own. A thread on a subscription or key asks before it spends Capy credits.
Organizations that set up keys and access rules before connections existed were converted once: every key became an organization connection covering that company's models, a rule that turned a model off stays **Off**, one that allowed only a subscription unchecks the model on Capy credits and on the organization's keys, and one that allowed only the organization's keys became **Only** that key. Saved model choices keep working: a thread that picked `codex/gpt-5.5` still runs on Codex, and one that picked `openai/gpt-5.5` while its owner holds a Codex subscription now runs on the subscription, because it is first in the list.
Yes. Connect a Codex, GitHub Copilot, or SuperGrok subscription, or an Anthropic, OpenAI, xAI, or Google key, under [Settings → Models](https://capy.ai/settings/models). The models it covers run on it and the rest run on Capy credits. When a subscription is used up, the thread asks before spending Capy credits; a key with no credit left fails the message until you top it up. See [connections](#connections).
Yes, from the billing page. Every plan change applies immediately and may include a prorated charge. Canceling instead keeps the current plan active through the end of its billing cycle.
Annual plans bill upfront for 12 months at a 20% discount. Credits are still granted monthly.
No, you can add balance directly (minimum \$5). A plan grants credits monthly at a discount.
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.